Same Model, Different Harness: CUGA, Hermes, and Deep Agents — When to Pick CUGA?
CUGA Policy Playground
Two live CUGA agents, with and without policies
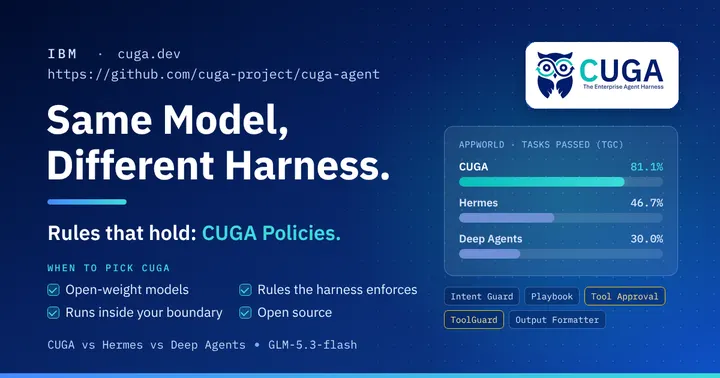
There are nearly 200 agent harnesses to choose from. We gave three of them the same open-weight model and 90 AppWorld tasks, and changing the harness moved task completion from 30% to 81%. For enterprise use, CUGA adds what this benchmark does not test: rules that the harness enforces and deployment inside your own boundary.
Community lists such as awesome-agent-harness and best-of-Agent-Harnesses track nearly 200 of them, and they make one point clearly: the harness matters, not only the model. In one analysis that best-of-Agent-Harnesses cites, the same GLM-5.2 model went from 23% to 52% on SWE-bench Pro when only the harness changed.
So the right question is not "which harness is best?" but "which harness fits my workload, with my model?" Hermes from Nous Research is built for always-on personal assistants, and Deep Agents from LangChain for long, multi-step tasks such as research. Both are excellent at those jobs.
Enterprise work is a different job. Agents act on business systems, such as CRM and payments, and they must follow rules that hold whatever the model decides. CUGA (ConfigUrable Generalist Agent) is IBM's open-source harness built for that job, with open-weight or hosted models, inside your own environment, including sovereign clouds and air-gapped deployments. To measure what the harness adds, we kept the model the same and changed only the harness.
We ran CUGA, Hermes, and Deep Agents on AppWorld, a benchmark of multi-step tasks across 9 apps and 457 APIs, such as email, payments, and file storage. The apps are consumer apps, so AppWorld is a proxy: it tests a subset of the capabilities that enterprise automation also needs, such as logging in, reading API docs, paging through results, and changing state across several apps. Every harness used the same open-weight model, GLM-5.3-flash, on the same 90 tasks in 30 scenarios, with one attempt per task. All runs used the Harbor evaluation framework, and our setup is public in harbor-eval, our Harbor fork.
Figure 1. AppWorld, 90 tasks in 30 scenarios, GLM-5.3-flash for every harness. TGC: tasks passed. SGC: scenarios where all three variants passed.
How to read this. This is not a verdict on Hermes or Deep Agents. Neither was built for multi-app API work like AppWorld, and that is the point: the harness has to fit the job.
The most useful number is SGC. A scenario passes only when all three of its variants pass, so SGC rewards consistency, not a lucky run. Here the gap is larger: 20 scenarios for CUGA, 8 for Hermes, and 2 for Deep Agents.
Three limits apply. This is a 90-task sample on one benchmark, so the results may not generalize to other tasks. The setups were not identical (see the setup table above). And the runs did not use policies, so they do not measure policy enforcement.
In the 90-task comparison, the model was the same in every run, so the differences come from the harness. Every CUGA agent runs the same compact loop: prepare, call the model, execute, and repeat. The same loop scales from one CugaAgent with its own tools to a CugaSupervisor coordinating several agents, local or remote over A2A. These are the CUGA features that ran in the AppWorld setup, grouped by what they do:
find_tools searches for any other tool a step needs
With these features, the model makes fewer decisions, and the harness catches more mistakes before they reach the result.
Each step that the harness controls, like those in the list above, is also a place where it can check a rule.
Most teams write business rules, such as payment approval or keeping customer PII inside the organization, into the system prompt. A prompt is an instruction, not enforcement. The model can misread it, a user can talk the agent out of it, and an injected message can change it in the middle of a task.
CUGA policies move these rules out of the prompt and into the harness. We describe this policy layer in our ACM CAIS 2026 paper, Governance by Construction for Generalist Agents (arXiv). The policies act at four points in every run:
Guidance steers the model, but approvals and ToolGuards are enforced by the runtime. Put rules such as payment approval and PII handling in the second group, where they hold whatever the model decides.
You can see the difference yourself in the Policy Playground, which sends the same message to two live agents, one without policies and one with them:
Figure 2. For "Pay everything I owe.", the agent without policies paid $90, including a denied claim in collections. The agent with policies held the payment for approval, then paid only the $10 that was due.
Choose a harness as carefully as the model. In our comparison, the same model completed between 30% and 81% of AppWorld tasks, depending on the harness. For enterprise work, CUGA gives you:
CUGA is not the right harness for every job:
CUGA is for automating business work across APIs, apps, and web UIs, under rules you can enforce.
The CUGA team ran this comparison, and CUGA used an AppWorld configuration that the other harnesses did not. If you can configure Hermes or Deep Agents to do better, send a configuration to harbor-eval. We will rerun it on the same tasks and publish the results, whichever harness wins.